Check server logs before blocking millions of news tag pages
Summary
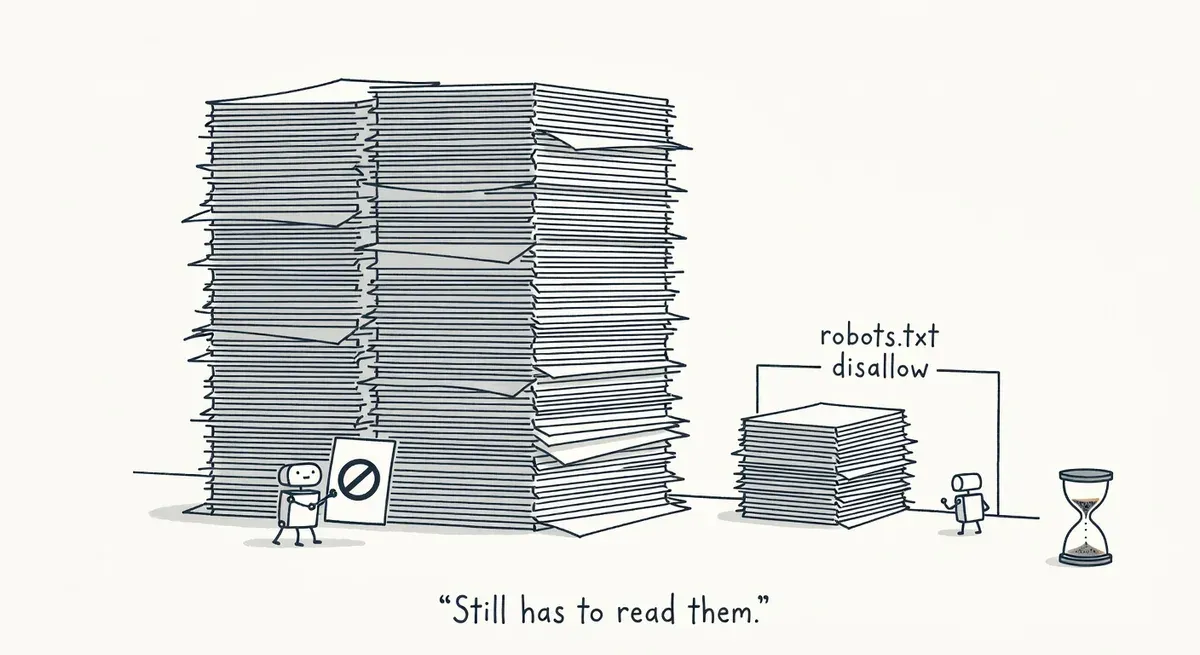
A robots.txt disallow saves crawl requests but can leave stub pages in Google's index. A noindex tag removes them, but only if the pages stay crawlable. Putting both on the same URLs cancels the noindex.
Neither directive is the right first step. A large count of tag and author pages does not prove Googlebot is missing fresh articles, so check server logs for where its requests go, then change one page type at a time.
An r/TechSEO thread on managing crawl budget for a news website asked whether tag pages and empty author pages should be disallowed in robots.txt. A large news site can have millions of these low-value URLs. The original post has since been deleted, but the replies are still up, and they agreed on a step that comes before either directive: confirm there is a crawl budget problem before blocking anything.
Disallow and noindex act at different stages
Google treats crawling and indexing as separate steps. Google’s guide to how Search works lists robots.txt rules as something that blocks crawling and robots meta rules as something that blocks indexing. Google’s robots.txt documentation describes the file as rules about which crawlers may access which parts of a site, and says Google may still index a disallowed URL and show it without a snippet.
A disallow saves fetches but leaves the URL eligible for the index. If Google finds links to a disallowed tag page, that page can still appear in results with no snippet. A noindex meta tag works the other way round. Google has to crawl the page at least once to read the tag, and after that the page drops out of the index.
The choice follows from the goal. To keep stub pages out of search results, noindex is the more precise tool. To stop Googlebot spending time on them, robots.txt does that job, but the site gives up control over what stays indexed.
What the commenters recommended
A commenter posting as rykef recommended noindex for the stub pages and suggested starting with an analysis of internal links. The argument was that news sites are crawled aggressively, so knowing which pages Googlebot finds quickly matters more than broad blocking rules.
Another commenter, AbleInvestment2866, split the two page types. Tag pages should generally be blocked or noindexed. Author pages are worth keeping when they have real content, and only the empty ones need handling. The same commenter added that unless a crawl budget problem can be confirmed, leaving things alone may be safer, because large changes to a news site’s URL structure carry risk.
That caveat is the most useful advice in the thread. Millions of tag URLs look like wasted crawl, but a high count of low-value URLs does not prove Googlebot is neglecting fresh articles. Only server logs show where its requests actually go. Empty listing pages can also cause a separate indexing problem, covered in an earlier piece on empty category pages triggering soft 404s.
What to do
- Read the logs first. The Screaming Frog Log File Analyser processes millions of lines of log data and shows which URLs and directories Googlebot crawls, when, and how often. The free version stops at 1,000 log events, so a news site’s logs need the paid licence at £99 a year. Search Console’s Crawl Stats report also breaks crawl activity down by response code. If tag and author URLs do not take a disproportionate share of Googlebot’s requests, the thread’s advice is to leave them alone.
- Use noindex for pages that should leave the index, and keep those pages crawlable:
<!-- On empty tag and author pages. Do not also disallow these paths in robots.txt. -->
<meta name="robots" content="noindex">- Set rules by page type. Empty tag pages and author profiles with no content are candidates for noindex. Author pages with bios and article lists may be worth keeping indexed.
- Audit internal links to stub pages. On news sites, tag and author pages often get thousands of internal links from article footers and sidebars. Fewer links to empty stubs can make Googlebot crawl them less aggressively, so start with the template changes that affect the most pages.
- Roll out in stages. One commenter in the thread put it this way: a site this size has more ways to get worse than to get better. Noindex one page type first, watch crawling and indexing, then expand.
Watch out for
Putting noindex and a robots.txt disallow on the same URLs defeats the noindex. Google cannot crawl a disallowed page, so it never sees the tag, and a page that is already indexed may stay indexed. Take a made-up example: a news site adds noindex to every URL under /tag/ and, in the same release, adds Disallow: /tag/ to save crawl. Googlebot stops fetching the tag pages, never reads the new tag, and the tag pages already in the index stay there. Pick one directive per URL pattern.
Sitemap generators that list every tag and author page cause a quieter version of the same problem. The noindexed URLs keep appearing in the sitemap, and Googlebot may keep requesting them. Exclude noindexed patterns from sitemap generation.