AI Crawler Management
Blocking training bots, allowing retrieval bots, AI-specific robots.txt.
- News
Google explains how to let Google-Agent past your bot defenses
The new help doc lists the user agent, IP file and Web Bot Auth signature to check, and the rule priority, CAPTCHA and API gaps that still block agents.
- News
United Airlines bans AI agents in its terms but not in robots.txt
United Airlines' 11 November terms require written permission for any automated agent and bar grounding AI models on its fare data, with search indexing exempt.
- News
OpenAI pays Cloudflare for hints on which pages changed
Matthew Prince told Cloudflare's Q3 call the crawl-efficiency deal is already booking revenue, with no word on whether the pilot's websites get a share of it.
- News
Brave sells your pages to AI and robots.txt can't block it
Brave's crawler advertises no distinct user agent and borrows Googlebot's permissions, so noindex is the only exit from the index it licenses to AI companies.
- News
Cloudflare now lists AI agents by name and lets you block each one
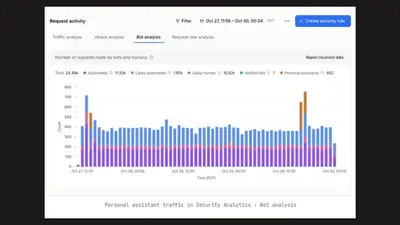
Cloudflare's Security Analytics now lists AI agents by name with request counts, and each supported agent can be allowed, blocked, or blocked on pages with ads.
- News
Cloudflare's managed robots.txt leaves ChatGPT search allowed
A study of 13,938 robots.txt files splits vendor defaults from hand-written rules: sites on Cloudflare's managed file almost never block OAI-SearchBot.
- News
Perplexity's crawler hit 70 English URLs and none in Turkish
One site's IP-verified logs show PerplexityBot requesting 70 new English paths in 26 seconds and none of the matching /tr/ hreflang alternates in the sitemap.
- News
Google, Microsoft and OpenAI will honour one AI training opt-out
The __usage_ai-training group states a training preference, but Google reads it as a Google-Extended block and Bing retires NoArchive as a signal on 1 March 2027.
- News
AI visibility vendors leave their own sites open to AI crawlers
An r/TechSEO audit fetched robots.txt and llms.txt from 118 AI visibility vendor sites: 64 publish llms.txt, and no AI crawler is blocked on more than one site.
- News
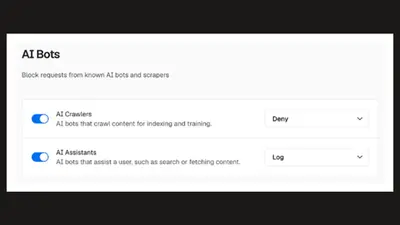
Vercel adds separate blocking for AI crawlers and assistants
Vercel's firewall now takes one action for training crawlers such as GPTBot and another for AI search fetchers such as OAI-SearchBot. Applebot counts as a crawler.
- News
Bot protection blocks AI crawlers that robots.txt lets through
An HTTP Archive pull across 457,000 German home pages, plus a 100-shop crawl test, shows bot protection refusing a crawler that robots.txt never blocked.
- News
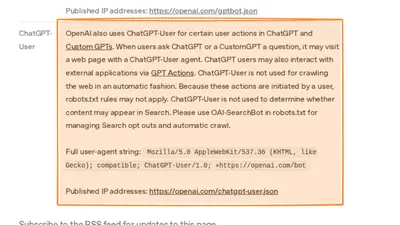
Chatbot page fetches skip analytics and show only in server logs
A test of 23 AI tools logged ChatGPT-User, Claude-User and MistralAI-User fetching pages server-side, while Comet and ChatGPT's agent looked like Chrome.
- News
Google's robots.txt parser silently drops lines it can't read
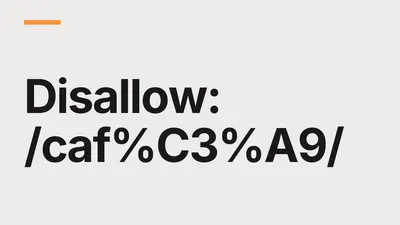
Google's robots.txt video confirms the parser accepts only user-agent, allow, disallow and sitemap, and advises percent-encoding for non-ASCII paths.
- News
Nine sites block GPTBot but let OpenAI's search bot crawl
A Reddit test resolved 19 AI user agents against robots.txt on 122 well-known sites. Bytespider drew the most blocks and user-triggered fetchers far fewer.
- News
Nearly half of llms.txt files a status check finds are error pages
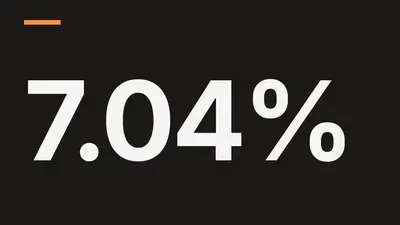
A daily crawl of 128,315 EU domains found 7.04% serving an in-spec llms.txt, under half what a status-code check reports. Two checks fix the count.
- News
Meta's Oct 30 terms let it train AI on any business user's site
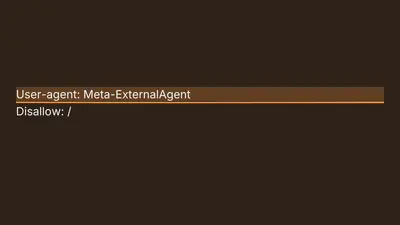
Meta's terms from 30 October grant crawl and AI training rights over any business using its products. Block Meta-ExternalAgent and keep Meta-WebIndexer allowed.
- News
Cloudflare now scores verified bots on robots.txt and 429s
Cloudflare's new trust bands track whether a verified bot honors robots.txt under RFC 9309 and slows after an HTTP 429, with the scores heading to Radar later.
- News
Cloudflare feeds OpenAI's crawler pages it had not found
A July 2026 pilot on about 1% of Cloudflare's network put hundreds of millions of pages into OpenAI's search index, so your crawl rules now decide what it fetches.
- News
Anthropic's test agents submitted real forms on live sites
Anthropic's report covers a false homicide tip to Philadelphia police, tokens lifted from a property map's settings file, and what that means for form endpoints.
- News
Grok hit one unlinked page from 59 IPs posing as Chrome or Safari
An r/TechSEO test gave each AI assistant its own unlinked URL behind a Cloudflare Worker, logging which ones read robots.txt and which arrived in disguise.
- News
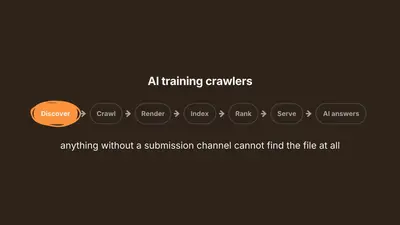
Mueller: AI crawlers only use sitemaps they find on their own
Google's John Mueller says AI training crawlers have no console for sitemap submission, and that his own server logs show them fetching his sitemap and RSS files.
- News
OpenAI's always-on agents browse with no published user agent
OpenAI's dots and Google's AI Mode monitoring both keep re-checking the web after the user leaves, and OpenAI's bot docs name no user agent for a dot's browser.
- News
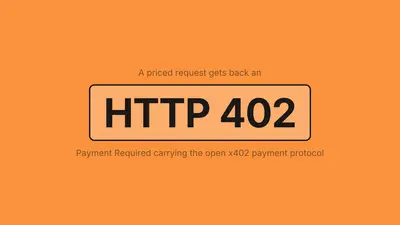
Cloudflare tests charging AI agents instead of blocking them
Cloudflare's Monetization Gateway lets a site price agent requests and answer with HTTP 402, but it is a US-only closed beta, so the job today is measuring bots.
- News
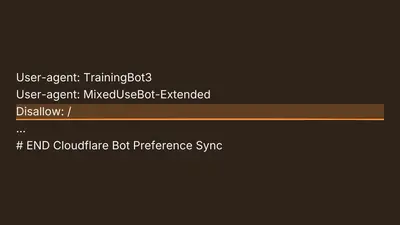
Cloudflare's AI training block now stops Googlebot too
Since September 15, Cloudflare's Training block also shuts out Googlebot, Bingbot and Applebot. Disallow AI Training refuses training and keeps search.
- News
Robots.txt only stops AI crawlers that choose to obey it
Reverse DNS for Googlebot, OpenAI's published IP lists, and CDN rate limits deal with the AI bots a Reddit thread found hitting parameter URLs despite robots.txt.
- News
A WordPress host silently blocked AI training bots on one site
Logs and curl tests in Search Engine Land show WP Engine refusing ClaudeBot, GPTBot and Amazonbot while PerplexityBot got through, plus a test for your host.
- News
Google signs some AI agent requests so sites can spot fakes
Google's experimental Web Bot Auth signs some Google-Agent requests with keys published at agent.bot.goog, yet Google still says to keep IP and reverse DNS checks.
- News
Cloudflare can redirect AI training bots to your canonical URLs
The AI Crawl Control toggle sends GPTBot and ClaudeBot a 301 to same-origin canonicals, so every page canonicalized elsewhere drops out of their crawls.