Latest Technical SEO News - Page 7
Crawling changes, algorithm updates, rendering fixes, and structured data developments as they happen.
-
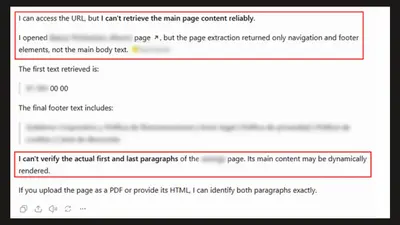
ChatGPT, Claude and Perplexity still see only your nav and footer
A 434-day retest of five AI platforms on JavaScript-rendered pages, with the verbatim replies and why Gemini and Copilot mostly succeed where live fetchers fail.
-
Nearly half of llms.txt files a status check finds are error pages
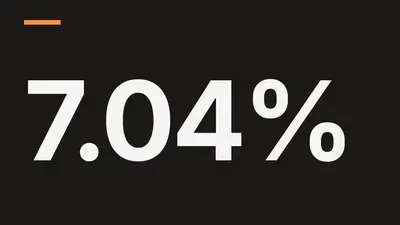
A daily crawl of 128,315 EU domains found 7.04% serving an in-spec llms.txt, under half what a status-code check reports. Two checks fix the count.
-
AI-readiness tools check that schema exists, not that it works
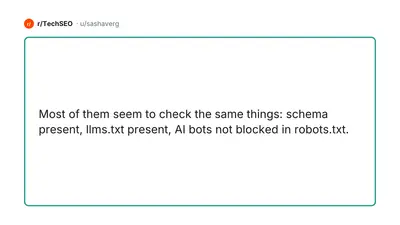
An r/TechSEO thread lists four correctness tests AI-readiness scorers skip, including noindex behind a robots.txt disallow and Markdown served by user agent.
-
Meta's Oct 30 terms let it train AI on any business user's site
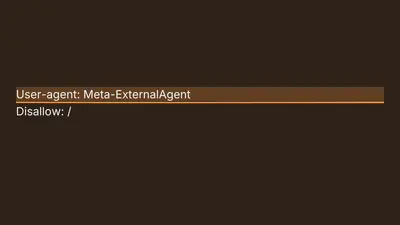
Meta's terms from 30 October grant crawl and AI training rights over any business using its products. Block Meta-ExternalAgent and keep Meta-WebIndexer allowed.
-
Unproven theory blames stalled migrations on site quality
Consultant Marie Haynes says a hobby blog whose redirects, canonicals and Change of Address checked out sat at crawled, currently not indexed for four months.
-
ChatGPT's utm outage hid far more clicks than it lost, logs show
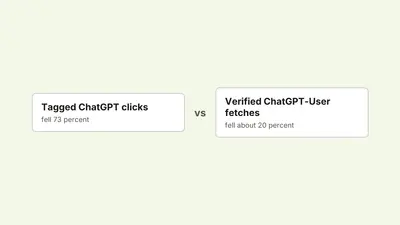
One shop's server logs show tagged ChatGPT clicks fell 73 percent in the utm outage while ChatGPT-User fetches fell 20 percent. Most of the loss was tags.
-
Facts placed only in schema came back in zero of 12 AI answers
Botpresso put author and founder details in JSON-LD and Microdata only and asked ChatGPT, Perplexity, Claude and Gemini about them. Zero of 12 answers found them.
-
Google's new shopping cart hands stores a copy with no sync
Universal Cart is live in US Search and the Gemini app, with a one-way CreateCart handoff and a native checkout option to pick in Merchant Center's UCP hub.
-
Google's Indexing API docs no longer say how to raise quota
Google deleted the approval form and testing-quota wording from three Indexing API pages this week, but the 200-a-day publish cap is still documented.
-
Cloudflare now scores verified bots on robots.txt and 429s
Cloudflare's new trust bands track whether a verified bot honors robots.txt under RFC 9309 and slows after an HTTP 429, with the scores heading to Radar later.
-
Semrush's Claude connector reads audits but cannot start a crawl
The Semrush MCP pulls completed Site Audit runs into Claude, and each past audit costs 10,000 of the 50,000 API units a qualifying plan gets per cycle.
-
Testers preferred AI-written search pages to Google's top result
A Google Research paper generated whole result pages with HTML and JS, and iPullRank's replication shows why rank tracking needs sampled ranges, not positions.
-
Cloudflare feeds OpenAI's crawler pages it had not found
A July 2026 pilot on about 1% of Cloudflare's network put hundreds of millions of pages into OpenAI's search index, so your crawl rules now decide what it fetches.
-
llms.txt showed no link to AI citations across 300,000 sites
SE Ranking modeled citation frequency across 300,000 domains, and dropping the llms.txt variable made the model more accurate. Check crawl access first instead.
-
Next.js 16.4.1 fixes two bugs that let attackers run code
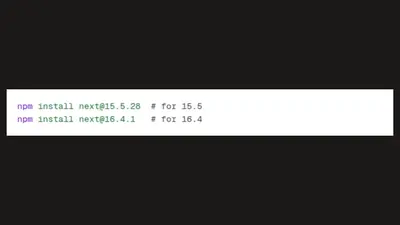
The Image Optimization API inherits a sharp memory bug on glibc Linux, and crafted requests can pin any App Router app with a Server Action at full CPU.
-
Google: keywords in URLs are an incredibly small ranking signal
Google's first Non-Canonical Cabinet video covers why hyphens still beat underscores as word separators and what percent-encoding does to emoji in paths.
-
No test behind the claim that URL paths change AI citations
An r/TechSEO post argues topic-based URL paths help AI crawlers group pages, offers no data, and a commenter counters that information structure does the work.
-
Shopify's agent tools answer returns, not arrival dates or pickup
Bill Hunt's audit of 122 Shopify storefronts queried the built-in policy tool with six buyer questions and opened 74 live checkouts to see what agents get.
-
ChatGPT clicks now show up as direct traffic in analytics
OpenAI's GPT-6 opens ChatGPT links with no UTM tag and no referrer, so clicks land in direct traffic. One analysis of 500 pages shows direct absorbing most of them.
-
Google recrawls PDFs slowly, so publish updates at a new URL
Google's Martin Splitt and John Mueller explain how PDFs are converted to HTML, why embedded images miss Image Search, and why an updated PDF needs a new URL.